
Worse-Than-Average Effect – when you assume you're worse than others at difficult tasks
Do you assume everyone else is better than you at difficult tasks? That’s Worse-Than-Average Effect – the tendency to underestimate your own competence in challenging activities, even when you have the skills.
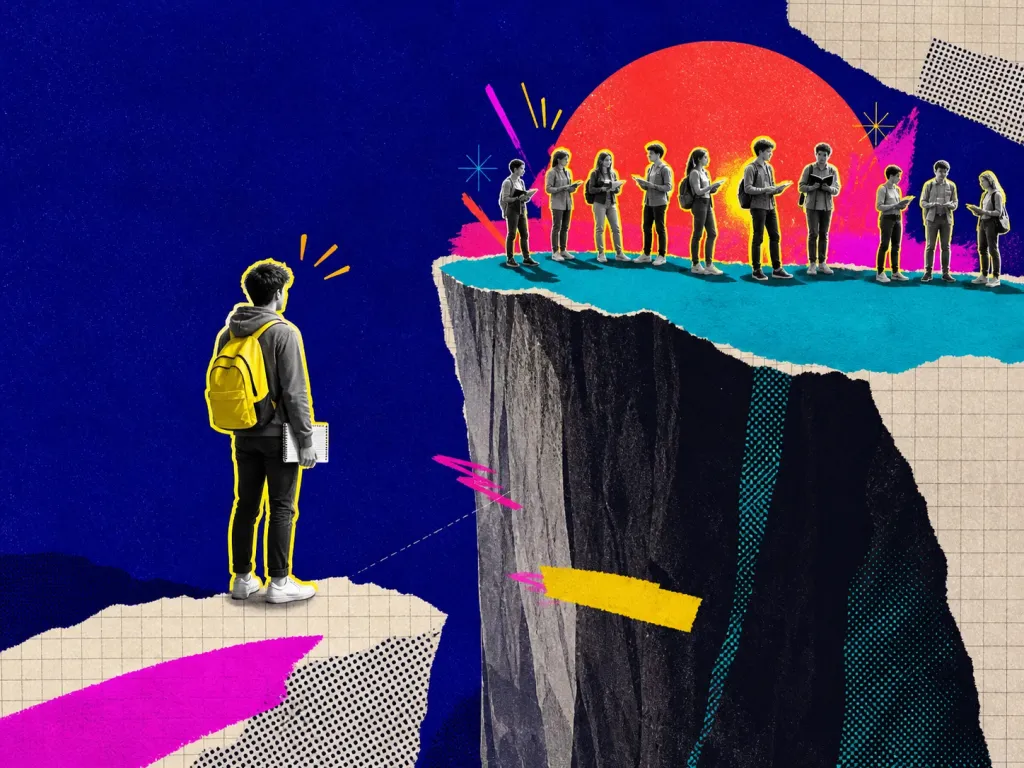
Examples and situations
- Studying & exams – you're sure you’ll fail the test, even though you studied as much as others.
- New skills – afraid to try programming, languages, or driving because ‘that’s for smarter people.’
- Work & career – you assume colleagues will figure things out faster, even when you start at the same level.
Questions to check
- Compare yourself to facts, not fears – you’re likely better than you think.
- Remember, hard things are hard for everyone – others may just hide their doubts better.
- Just start and see – experience will prove you’re more capable than you expect.
Long-form guide
“Everyone Else Seems Better”: The Worse-Than-Average Effect and Stop Shrinking Yourself
You walk into the climbing gym for the first time. Chalk hangs in the air. People with forearms like braided rope dance up walls that look vertical to you and insulting to gravity. You stare at a beginner route and feel your hands sweat. You’re sure you’re worse than the average climber in here. You almost turn around.
On this page
What Is the Worse-Than-Average Effect and Why It Matters
One sentence definition: the worse-than-average effect is when we assume we’re worse than others at difficult or unfamiliar tasks, often underestimating our own ability. We’ve seen this bias crush pitches, delay careers, and shrink hobbies into “maybe later” piles. We’re building a Cognitive Biases app because catching these mental blind spots in the moment beats learning about them after the regret. Let’s name it, see it, and work around it—in real life, with real examples. The worse-than-average effect says: when a task feels hard, ambiguous, or elite, we rate ourselves below average—even when we’re not. It’s the flip side of the classic “better-than-average effect,” which shows up for easy things like driving on empty roads or choosing ripe avocados. When the task gets tough, the mental seesaw tilts the other way (Kruger, 1999; Burson, Larrick, & Klayman, 2006).
It matters because it edits our lives before we even act. We under-apply, under-speak, and under-try. We avoid advanced classes, senior projects, stretch assignments, or big creative experiments. We also fail to practice the right way—because if you’re “bad,” why invest? That’s not humility. That’s a false map. Three quiet damages stack up: You miss opportunities. Self-screening beats external rejection by a mile; You practice less and stagnate. Sunk motivation is sneaky; You share less, so you get less feedback. No feedback, no calibration. It’s practical to understand which tasks trigger this bias and how to drag your estimate closer to reality. Once you know the shape, you can step around it—like a puddle you no longer mistake for a lake.
Why We Slip Into It
We’re not broken; we’re Bayesian with weird inputs. Several forces push us down the slope: Hard tasks expose your ignorance in sharp detail. You know every way your code could break. You don’t know how often other people’s code breaks. That asymmetry breeds underestimation (Kruger, 1999); You don’t see the average performer; you see the highlight reel. You compare your draft to someone else’s published book. That’s apples to apple pie; The harder the task, the fuzzier the scale.
Without a shared yardstick, you assume your clumsy steps are below the mean (Burson et al., 2006); Social comparison skews toward experts. You follow pros, not peers. Your sample is biased; Fear of social cost. Understating feels safe. It’s a hedge against being seen as cocky or wrong; The calibration trap. People tend to be overconfident on easy items and underconfident on hard ones—the hard–easy effect (Lichtenstein & Fischhoff, 1977). Put together, you get believable self-doubt that feels like realism. It’s not realism. It’s realism’s cautious cousin who never leaves the house.
The new engineer who dodges code reviews
Leah joins a backend team that worships code clarity. She’s shipped small APIs alone before. Now, every pull request goes under microscope-grade lenses. She lurks in review channels and sees elegant suggestions from seniors. She decides her work is “not ready” yet. She delays her first PR by two weeks, overpolishing variable names while architecture decisions gather dust.
When she finally posts, the review is kind, focused, and short. Her biggest issue? She didn’t ask earlier. The team had reusable patterns she never found because she kept her code hidden. The worse-than-average effect made her hide the exact mistakes that would have taught her the team’s tastes.
The product manager who stays quiet in cross-functional calls
Tash plays complex fingerstyle alone at night. On Instagram she follows players with 12-string monsters and flawless tone. She records a minute of a song and deletes it. “My right hand’s sloppy. Everyone else sounds clean.” She never posts. She never gets the “hey, your dynamics are special” comments that would become her lane. Her strength needed social oxygen. The bias turned the airflow off. Riya switches from a startup to an enterprise team with a hundred PMs. She watches seasoned folks speak in polished frameworks. She used to sketch ideas on a whiteboard and ask dumb questions. Now she keeps a doc open with citations and says nothing.
Her assumptions: “They’ve seen all this. My thought is probably obvious.” She’s wrong. The only person with her exact knowledge of users doesn’t speak, so the team ships a feature with the wrong default. Underconfidence made the product worse. It also made Riya feel invisible.
The grad student who avoids presenting
Luis moved cities and booked a conversation class in Japanese. He opens the group chat and sees people texting in kanji. He’s still wrestling with counters for flat objects. He cancels. He tells himself he’ll practice a month first. A month later, he quits. The class would have chunked the skill into do-able parts. The bias told him the mountain was unclimbable in public. So he never starts.
Nina does solid work on a gnarly Bayesian model. She sees a seminar filled with people who talk like they were born in latex. She feels like a tourist holding a rail map. “I’m worse than average at presenting this.” She swaps to a poster session, then to nothing. A year later, someone publishes a nearby idea. She whispers “I had that.” But whispers don’t shape careers.
We mis-read scales
You know the caveats and hacks that kept your last sprint alive. You rarely see what kept other people afloat. Result: your flaws feel signal; theirs feel invisible. This is the asymmetry at the core (Kruger, 1999). We think of “people who do X,” and our mind pulls up experts. Think of “runners”—you see marathon finish lines. Think of “artists”—you see gallery walls. Comparisons to the 90th percentile make your 55th percentile feel like the 10th.
If the scale has no shared ruler, you underweight your skill. Burson et al. (2006) showed that the way the scale is framed changes how people judge where they stand. Without standard benchmarks, we drift low or high depending on the task.
Recognize It, Before It Shrinks You
If something feels hard, we assume we are the problem. Sometimes the problem is the terrain. The first mile of a new skill has rocks and roots. That’s the terrain doing terrain things. It’s not your shoes. Publicly being wrong stings. So we understate our ability to lower expectations. That move can be rational socially but costly privately; it chokes stretch chances. Watch for moments when your self-rating plummets without fresh evidence. Catch yourself in the language. “Everyone else is probably…” “I’m not good at this compared to…” “They’ve likely thought of this already…” If your brain keeps saying “compared to,” ask “compared to who?”
Look for stalls. Delay is a symptom—when you “prepare” past the point where feedback would help more than polishing. Notice when you only practice to avoid exposure, not to improve. Finally, watch who fills your mental room. If it’s all experts and none of your peers or past self, your comparison lens is warped.
Build your own baseline fast
You don’t need blind confidence. You need a working process that forces reality to check you. A few concrete moves: Before comparing to “others,” pin your own numbers. Put down a stopwatch, a test suite, a mock interview, a three-problem set. Get a read in an hour, not a month.
Code: solve three typical tickets; log hours and bugs per ticket; Writing: draft a 600-word piece; count edits to clarity, not style; Music: record one take; note timing drifts at the 30-second mark; Language: hold a 5-minute conversation on daily topics; track stuck points. Now you’re comparing you to you. That’s a fair fight.
Use objective ladders, not vibe scales
Follow one or two top experts for inspiration. Follow ten peer-level folks for calibration. Your brain needs to see normal struggle. If you can’t see peers, create them: join a cohort, form a practice group, or pull three strangers off a forum into a weekly call. “Average” gets visible only when you make a small average. Invent a ladder that forces discrete steps. For example:
Guitar: 60 bpm clean at 8 bars; 70 bpm; 80 bpm; Data viz: complete chart types A, B, C with a fresh dataset in 2 hours each; Product: ship 1 small experiment per sprint; then 2; then an experiment with >5k users. When the ladder is clear, your brain argues less about “average.”
Ask for percentile placement, not adjectives
Set a simple rule: publish, present, or request a review by day X, no extensions. If it’s not ready, publish a smaller thing. Don’t give your fear infinite runway. The rule can be as light as “I submit one PR by Wednesday no matter what.” In three weeks, you’ll be less wrong about your actual competence than any private guess.
Feedback like “you’re doing okay” lands mushy. Ask: “Roughly what percentile would you put me on [this task] among juniors?” People won’t be perfect, but the signal beats vibes. A manager saying “you’re around 60–70th percentile” punctures a lot of quiet myths.
Track deltas, not absolutes
Bet small money or points on predictions. “I think I’ll pass 6/10 of these interview questions.” You’ll quickly calibrate. Missing the mark is the win—you get truer faster. Keep stakes small but real. Present a 5-minute whiteboard, not a full talk. Publish a 300-word note, not a manifesto. Play one verse on camera. Narrow slices make comparison sane.
Keep a “gains” log: what used to take 3 hours now takes 1; this refactor got 2 fewer comments than last time; the metronome moved 12 bpm in three weeks. Growth stories beat static labels.
Teach one step behind you
“Average” among whom? If you’re writing docs for new teammates, the good comparison isn’t literary Twitter. It’s “Can a new hire find the edge cases?” Define the audience and your criteria shrinks from vague prestige to concrete utility. If your field has belts, grades, rubrics, or checklists, use them. When you clear belt orange, you can stop arguing with your gut.
Teach the thing you just learned. It exposes what you actually know and re-centers your comparisons on someone yesterday-you can help. If you say “no” to three or more, you’re likely in the worse-than-average fog. Pick two items and change them this week.
Academia and research
New languages, performance tuning, and anything with footguns feel hard. Your brain flags “I must be worse.” Counter it with micro-benchmarks, pair programming with juniors and seniors, and a weekly PR cadence. Ask reviewers for percentile on readability and test coverage, not just thumbs. Design, writing, music—public output breeds comparison. Use a “studio hour” rule where the goal is to finish one thing that serves one persona. Collect peer-level newsletters, playlists, zines. Watch process streams so you see the mess, not the gallery.
Everyone sounds fluent because the domain rewards fluency. Run lab meeting reps. Present 5-minute slices. Keep a slide bank of “I got X wrong, here’s the fix.” Demand rubrics from advisors. If none exist, propose one for your lab.
Better-than-average effect: Worse-Than-Average Effect
The field fetishizes “vision” and outcomes. Hard tasks get fuzzy. Cut to loops: one experiment per sprint, minimum sample size, a decision rule written beforehand. Meet monthly with two peer founders for normalizing. Hard tasks feel humbling body-first. Film drills and track speed/accuracy. Compete or converse just above comfort.
If your comparisons are Olympic, your motivation is doomed. Switch to league tables and A2/B1 standards. Opposite cousin. For easy tasks like driving, we overestimate ourselves. For hard ones like public speaking, we move under. Both are about comparative judgments skewed by task difficulty (Kruger, 1999).
Dunning–Kruger effect
Feeling like a fraud despite evidence (Clance & Imes, 1978). Overlaps: you doubt your competence among high-achievers. Difference: impostor feelings persist across evidence; worse-than-average is tied to task difficulty and comparison frames. People are overconfident on easy questions and underconfident on hard ones (Lichtenstein & Fischhoff, 1977). It’s about probability calibration; worse-than-average is about comparative self-placement. They often travel together. We think others notice our flaws more than they do. Feeds the fear machine that powers under-claiming. Unlike worse-than-average, it’s about perceived attention, not ability.
Beginners may overestimate because they lack knowledge to see mistakes; experts sometimes underrate because they know too much (Kruger & Dunning, 1999). Worse-than-average can bite anyone when tasks feel hard—even competent people. Don’t throw Dunning–Kruger at everything.
A Field Note From Our Team
When a negative stereotype about your group is activated, performance drops. It’s a social pressure, not a perception bias. But it can magnify worse-than-average feelings in the moment. We ignore differences in who we’re comparing to. If your “average” is senior-only, you’ll always be below it. We’ve watched this bias clip the wings of people who could fly. We’ve also watched it sneak into our own sprints. A few of us delayed releasing a small feature because “other apps do this better.” Then we shipped, got a few “this solved my Tuesday” notes, and realized we’d been comparing our V1 to someone’s polished V5.
It’s why we’re building a Cognitive Biases app: gentle nudges when your brain does predictable brain things. The app won’t teach guitar or code for you. But it will say, “Hey, this looks like a hard-task underestimation. Want to sanity-check with a rubric or ping a peer?” That tiny friction can keep you from shrinking yourself right before your next step.
Step 3: Run a 60-minute pilot with a peer
You asked for practical. Here’s the long version we use with mentees. “I want to deliver a 10-minute product update to engineers and designers.” The audience sets the scale. The task sharpens the work. Example: “Slides arrive 24 hours early. I cover the three metrics that changed. I propose one decision and one next step.” Keep it un-fancy.
Don’t rehearse alone until you run out of air. Grab a peer. Do it once. Ask, “Where did you get bored? What was unclear? What percentage would you say this is of a typical solid update?” Don’t defend. Note and adjust.
Step 7: Adjust your ladder
Put it on the calendar. Do not extend. If the scope is too big, cut scope, not the date. Pick two that matter. For the update: “Questions per minute” and “Decision made? Y/N.” For code: “Review comments that triggered changes” and “Cycle time.” For writing: “Retention past 30 seconds” and “Replies per 100 readers.” Numbers puncture fog. “I paused less and the decision landed.” “I got fewer nits on naming.” “Two readers said they used it.” Gains push back on the “I’m worse” story.
If Step 5 numbers are weak, change the practice, not the schedule. Maybe present to a smaller group next time, or pre-read more data. The goal is a tight loop. Do this three times in a month. Your brain will recalibrate whether it wants to or not.
“My Benchmark Was Wrong”
A designer we’ll call Zee kept shelving small enhancements. “The senior folks have surely considered this. If it hasn’t shipped, I’m missing something.” We asked her to write the RFC in 30 minutes and ping a mentor. The reply: “Great. We never prioritized this. Ship it.” Two weeks later, usage metrics ticked up. The gap wasn’t ability. It was assumed omniscience in others.
A junior data scientist compared herself to Kaggle grandmasters and cried on Sundays. We replaced her benchmark with “predict weekly churn 4 weeks out at baseline+5%.” She hit +3%. Then +7% with a simple feature. The room clapped, not because grandmasters would, but because the business needed +5%. Good enough wasn’t hypothetical.
Research, Briefly and Usefully
A PhD student thought his poster would look childish next to “real” labs. He set a rule to present five minutes at every group meeting. On week four, a visiting professor said, “Can I introduce you to a collaborator?” The bar wasn’t as high as he guessed. Or maybe it was, and he cleared it sooner than he thought. People rate themselves above average on easy tasks and below average on hard tasks (Kruger, 1999).
The difficulty flips the sign; How the scale is presented and who you compare to shape your self-placement (Burson, Larrick, & Klayman, 2006); Calibration is off in predictable ways: overconfidence on easy, underconfidence on hard (Lichtenstein & Fischhoff, 1977); Overconfidence and underconfidence sit on the same continuum and change with incentives and information (Moore & Healy, 2008). These aren’t just clever lab tricks. They name the patterns we feel before big moments.
Wrap-up: Don’t Shrink Before You Try
Somewhere, right now, you’re hiding a draft. It’s probably a little messy and surprisingly useful. The worse-than-average effect whispers that everyone else has already nailed this, that your shot will land flat, that you’re late. You’re not late. You’re in the hard part, where everyone who matters feels clumsy. Use ladders, baselines, and peers. Timebox exposure. Ask for percentile, not praise. Track gains like you would wins in a game. Let your next small public thing be the one that snaps your perception back to earth.
We’re building our Cognitive Biases app to give you a nudge when your brain leans into old patterns. Not to hype you up, but to quietly suggest, “Hey, this might be the hard-task trap. Want a rubric? Want a peer check?” You’ll still do the work. You’ll just do it in daylight, not under a blanket of assumptions. The average is not a cliff to fall off. It’s a line to cross and recross, on your way to something that looks like you.
How do I pick a fair comparison group?
Shrink the task to the smallest public slice with a timer. “Record 30 seconds, one take.” “Ship a PR touching one file.” Get signal. Schedule the next slice. Momentum beats mood. Name the terrain. Then translate “stupid” into a plan: “I can’t map X to Y yet. I’ll run two 45-minute drills on that mapping and ask one peer to watch.” Plans dissolve shame.
Choose by context and stakes. If your audience is teammates, compare to solid teammates. If your audience is customers at a specific tier, compare to products at that tier. Write the group down so your brain doesn’t swap in celebrities.
How can I help a teammate caught in this bias?
Steal from adjacent fields. A software rubric can look like “tests pass locally, coverage +X%, diff < N lines, complexity under M.” A speaking rubric can be “1 idea per slide, 3 moments of interaction, finish on time ±30s.” Keep it short and observable. Ask for bracketed guidance. “Would you call this below expectations, meets, or exceeds for someone at my level? What’s one behavior to move up a bracket?” If that fails, triangulate from two other seniors or peers. Offer a ladder and a small audience. “Show us a 3-minute demo next standup?” Give specific percentile or bracket feedback. Celebrate deltas, not just outcomes. Model public drafts.
Yes. The antidote to both is the same: external checks and clear benchmarks. If your numbers and feedback disagree with your vibe, adjust. Let reality be your coach. Yes—treat the “I’m worse” feeling as a cue to set a micro-exposure and ask one sharp question. Fear becomes a trigger for action, not avoidance.
Decision checklist
- Can I name the exact group I’m comparing myself to?
- Do I follow more experts than peers in this domain?
- Have I shipped anything small in the last 7 days?
- Do I have a personal baseline for this task (time, accuracy, tempo, throughput)?
- Have I asked a specific percentile-placement question to someone qualified?
- Did I set a non-negotiable exposure deadline?
- Is my ladder for progress objective and visible?
- Have I taught a piece of this to someone one step behind me?
- Do I keep a “gains” log with concrete deltas?
- Did I replace a vibe-scale with a rubric?
- Define the audience and task in one line
- Write three “good enough” criteria you can observe